
The command `wget -nv -O wget-robots.txt https://www.linuxfordevices.com/robots.txt` saves a 67-byte response under `wget-robots.txt`. I enjoy following the handoff from a web address to a named file on disk.
The URL and output name give you two useful points to follow through the command. Trace the request from that URL into Wget’s work.
What wget does
GNU Wget is a command-line downloader that fetches network resources without an interactive browser session. It writes the response to a local file, but it does not install that file or prove its publisher’s identity.
| Protocol | What Wget retrieves |
|---|---|
| HTTP and HTTPS | Web pages, archives, and other resources served over the web |
| FTP | Files served by an FTP server |
The basic form is a Wget command followed by a URL. The URL identifies the remote resource, while the current directory is the default destination.
Check whether wget is installed
Run the version command before adding a package.
wget --version
The first line identifies the installed version. The build details list enabled features, so a missing protocol can come from how Wget was built rather than from a mistyped URL.
If the shell reports that wget is not found, install the package named wget with your distribution’s package manager. On Ubuntu or Debian, the command is:
sudo apt install wget
Ubuntu’s package catalog lists wget as its network-retrieval package. If you need to check package names on an Ubuntu system, see how to list installed packages with apt.
Download one file and choose its name
Wget saves a response under its remote filename in your current directory. A URL by itself is enough to start the request.
wget https://www.linuxfordevices.com/robots.txt
I chose -O to save this response as wget-robots.txt instead of reusing robots.txt as the local filename.
wget -nv -O wget-robots.txt https://www.linuxfordevices.com/robots.txt
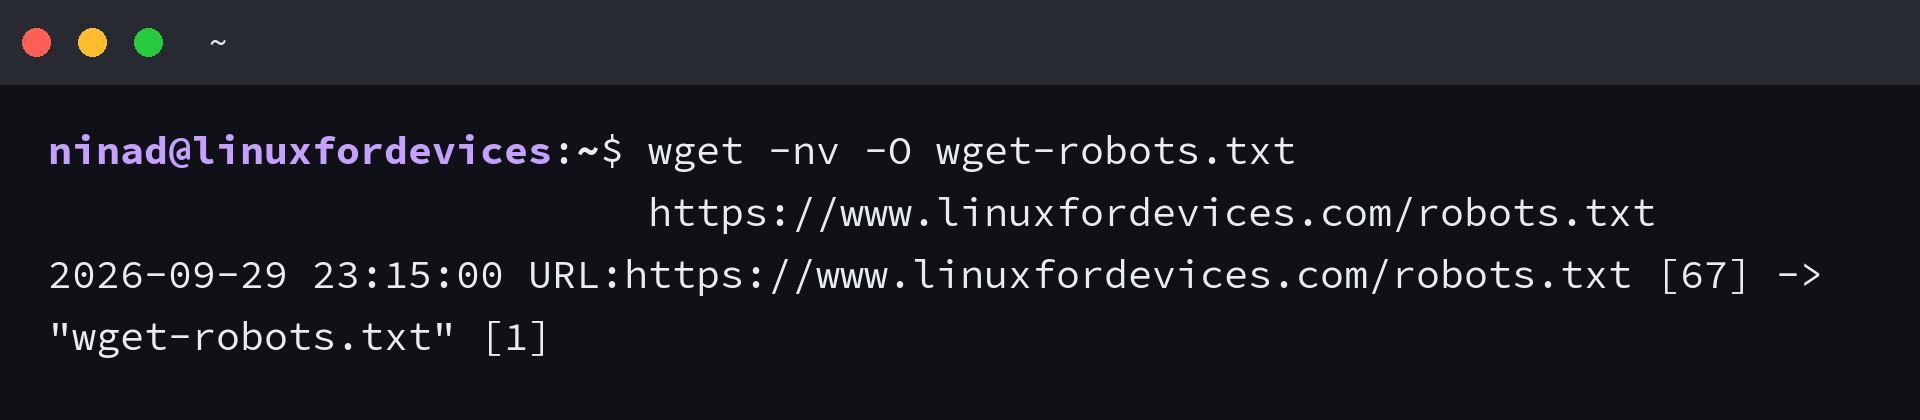
The -O option writes the response to one named file and truncates that destination when the request starts. It is not a resume switch, so do not point it at a partial file you intend to continue.
Use -P when you want to keep the server’s filename but save it under a particular directory. For a separate command-line approach to file downloads, see how to download a file with cURL.
Match the option to the task
-O selects an output file and -P selects a directory prefix, while –spider and –limit-rate change retrieval behavior.
| Task | Option | Effect |
|---|---|---|
| Save under a chosen name | -O FILE | Writes the response to one output file |
| Choose a destination directory | -P DIR | Saves files beneath a directory prefix |
| Check whether a URL responds | –spider | Checks the resource without saving its body |
| Read a list of URLs | -i FILE | Reads one URL per line and retrieves entries in sequence |
| Limit transfer speed | –limit-rate=500k | Limits retrieval speed to the requested rate |
| Run after the shell returns | -b | Runs in the background and writes a log |
| Retrieve a site recursively | –mirror | Enables recursive retrieval and timestamping |
| Limit recursive scope | -l N, –no-parent | Caps link depth and stays below the starting directory |
–mirror follows links across a site, so use it only on authorized content and cap its depth with -l N. The GNU Wget manual covers option interactions, and this Linux manual-page guide shows how to browse a local copy.
Resume only when the server supports it
Because Wget retries interrupted transfers during a run, use -c when a later command finds a partial file in the same directory.
wget -c https://www.linuxfordevices.com/robots.txt
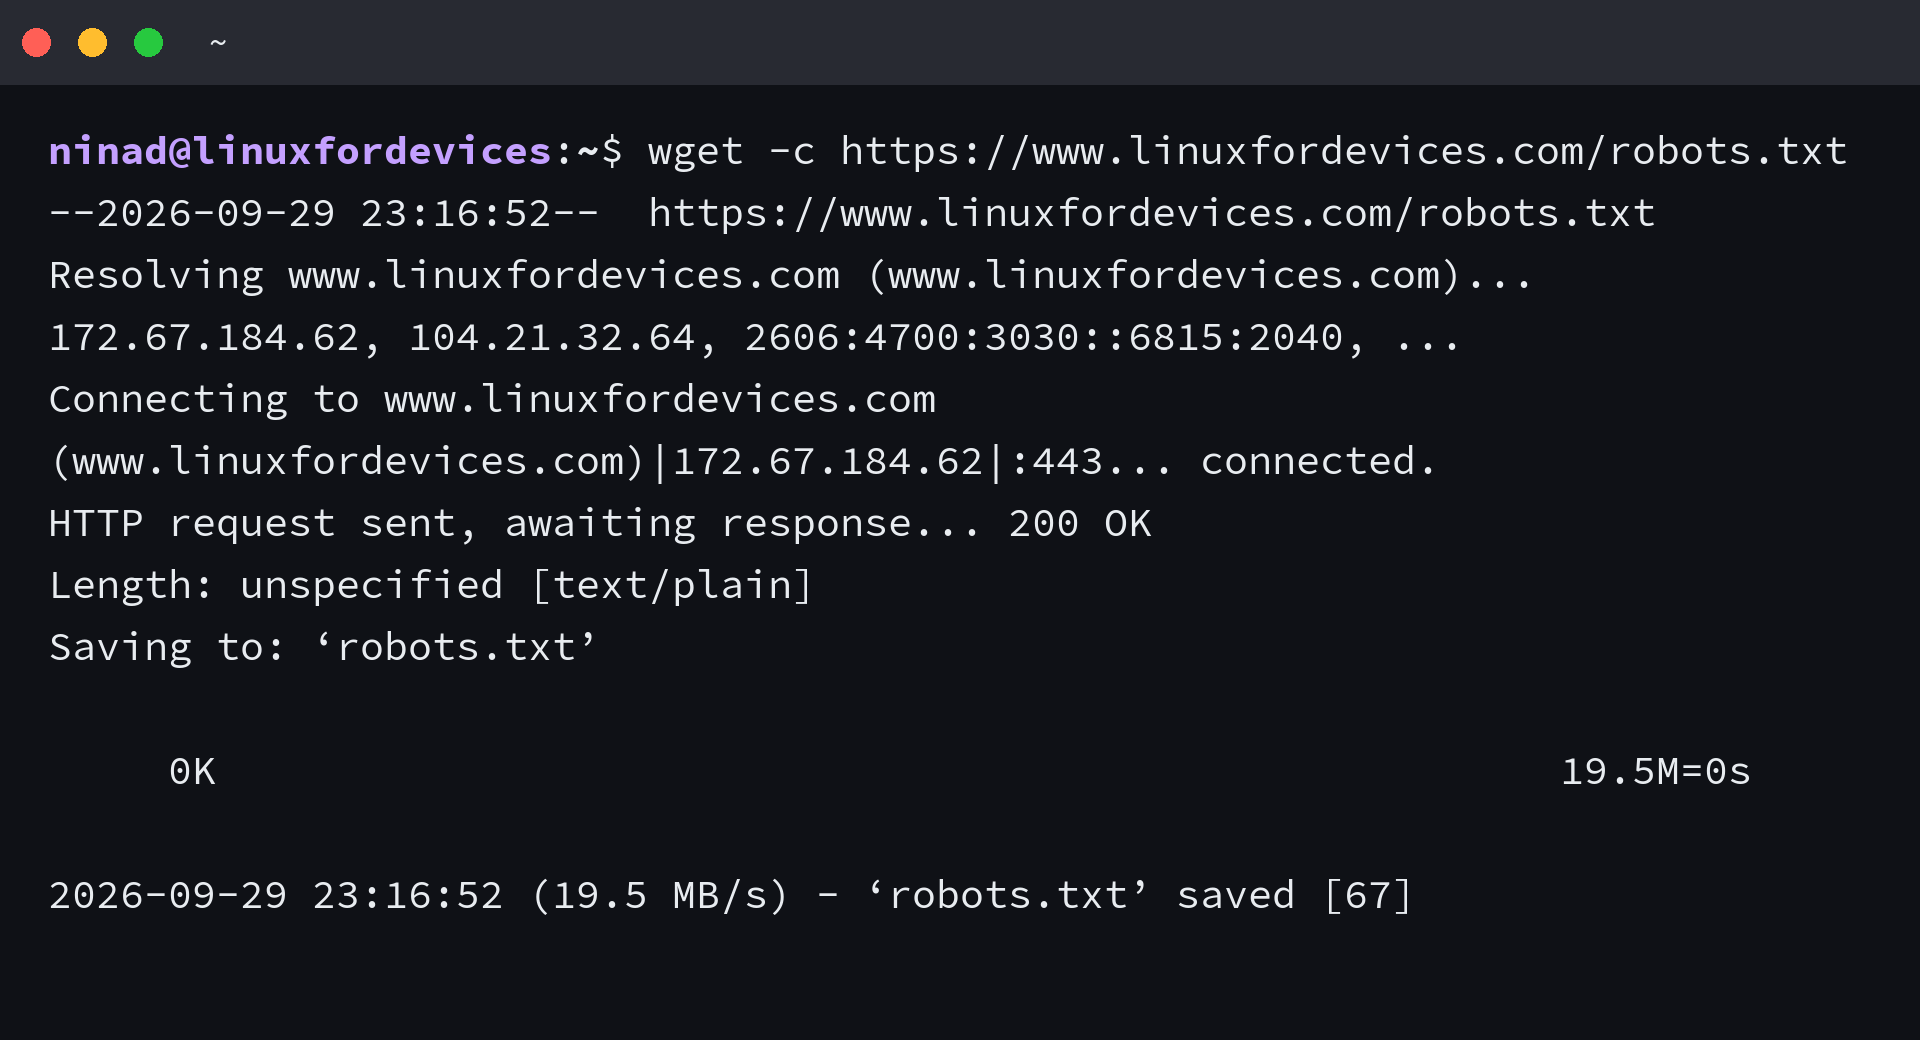
Continuation depends on server support, because 206 Partial Content carries the requested remainder but 200 returns the full resource.
I used -c with a 20-byte partial file, but the server returned 200 OK and Wget wrote all 67 bytes. That response shows a restart, not a 206 continuation.
Download a URL list without repeating commands
Put one URL per line in urls.txt, then pass it to -i so Wget retrieves each listed file in sequence.
https://www.linuxfordevices.com/robots.txt
https://www.linuxfordevices.com/tutorials/linux/linux-wget-command
mkdir -p list-downloads
wget -i urls.txt -P list-downloads
For automation from a Python program, see how to run Linux commands from Python and pass arguments without building a shell string.
Read the failure before changing flags
A server error and a local command-line mistake need different fixes. Start with the response Wget reports.
| Output | What it tells you | Next check |
|---|---|---|
| 404 Not Found | The server answered, but that path was not found | Check the path, filename, and redirects |
| Unable to resolve host | The name did not resolve to an address | Check spelling and DNS access |
| Certificate validation error | The TLS identity check failed | Check the system clock and certificate chain, and keep validation enabled for ordinary downloads |
| URL stops at an ampersand | The shell treated & as a control operator | Quote the complete URL |
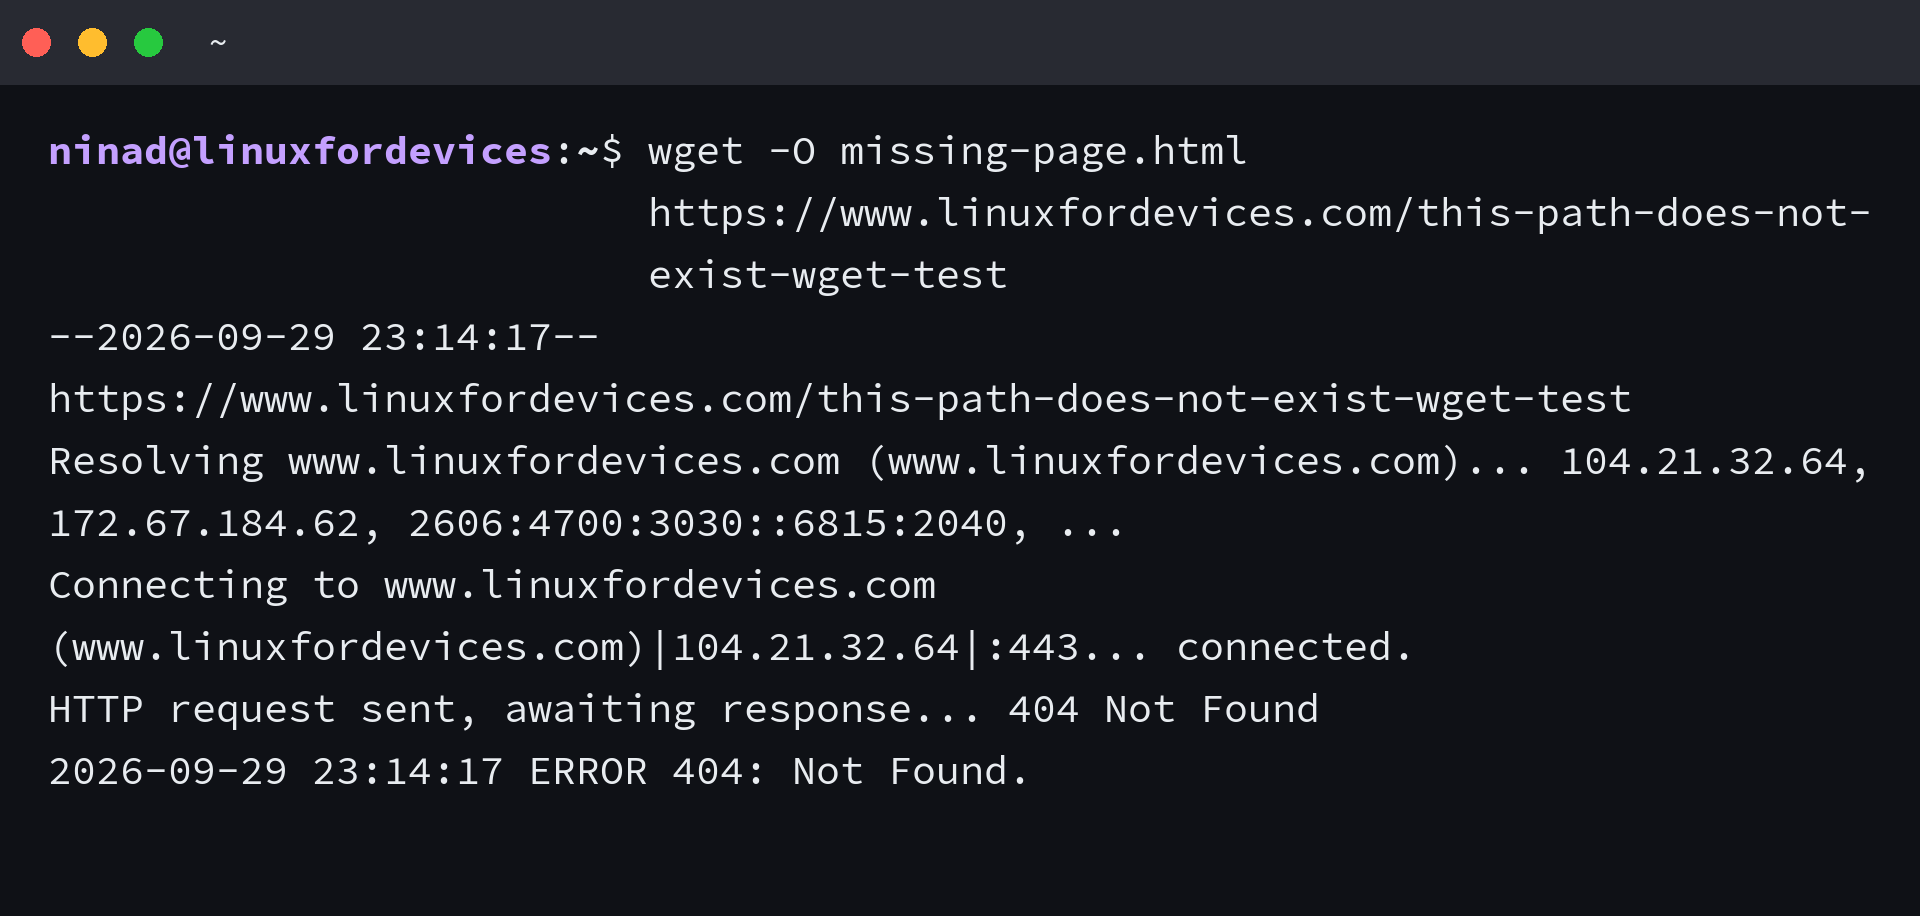
I used an intentionally missing path here, so the server returned 404 and Wget exited with status 8. Check the requested path before changing connection or certificate options.
wget -O missing-page.html https://www.linuxfordevices.com/this-path-does-not-exist-wget-test
Quote a URL that contains an ampersand so Bash passes the query string as one argument.
wget -O query-url.html "https://www.linuxfordevices.com/tutorials/linux/linux-wget-command?ref=wget&source=guide"
I quoted the full URL, so Bash passed both query parameters to Wget as one argument.
Check the downloaded file before using it
A zero exit status confirms that Wget completed the request, not that the file is safe or authentic. Check its type and compare a checksum with a value published by the source you trust.
file wget-robots.txt && sha256sum wget-robots.txt
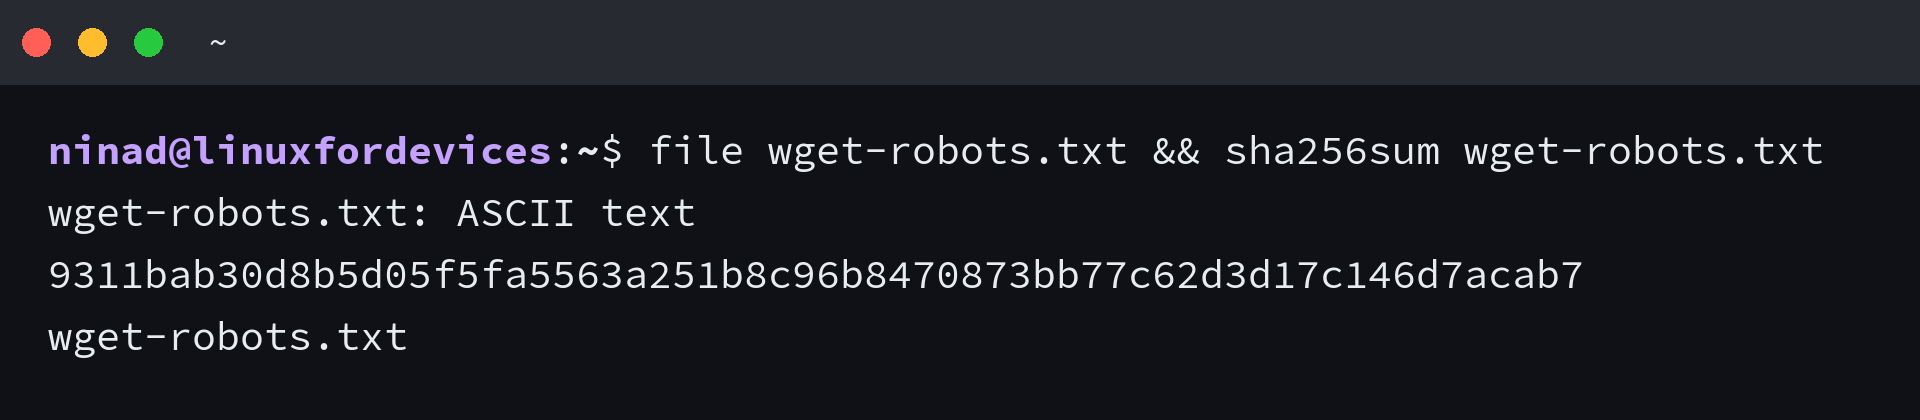
If the download is a tar archive, compare its local digest with the publisher’s SHA-256 value before extracting it with this tar guide.
Linux wget command FAQ
An absent command calls for a package install, while a partial transfer depends on whether the server can continue it.
How do I install wget on Ubuntu?
Use sudo apt install wget, then run wget –version to confirm the command is available.
Where does wget save files?
It writes to the current directory by default. Use -P DIR to choose a directory or -O FILE to write to a specific output file.
Does wget resume a failed download automatically?
Wget retries an interrupted transfer during the same run. Use -c on a later run when the server supports continued retrieval and the partial file is present.
What does wget exit status 8 mean?
Wget reports a server error response, such as HTTP 404. Check the response and requested URL before changing certificate or connection options.