
Working with text records at the shell can mean finding the rows and fields that matter. awk reads text records and lets you select fields or calculate totals.
I’ll show how to select fields and summarize matching records, then save the program in an awk file for reuse.
TL;DR: Use awk to select and reshape text
The awk command reads records and can select fields or calculate a total.
- Use a condition to choose which records to process and an action in braces to say what to do.
- Numbered field references select columns in the current record.
- Set the input separator before reading data, then use BEGIN and END for setup and final output.
- Save a longer program in a file and pass it with -f.
What does the awk command do in Linux?
An awk program is a sequence of rules, each with an optional condition and an action in braces.
| Term | Meaning | Example use |
|---|---|---|
| Record | One unit of input, usually one line. | Process a log entry. |
| Field | A part of a record separated from the other parts. | Read a user name from column one. |
| Condition | A test that decides whether a rule’s action runs. | Select rows where a numeric field exceeds a limit. |
| Action | Statements that print or transform data. | Format columns or add to a total. |
| Field references | $0 is the whole record. Numbered references select its fields. | NF counts fields and $NF selects the last. Use $(NF-1) for the second-last, since $NF-1 subtracts one from the last value. |
awk normally sends results to standard output and leaves the input file unchanged. For direct substitutions within lines, sed may be a closer fit.
| Option | Purpose |
|---|---|
| -F separator | Set the input field separator before records are read. |
| -f program.awk | Load rules from a program file. |
| -v name=value | Assign a value before BEGIN runs. |
Put a short inline program in single quotes. Use -f when a longer rule is clearer in its own file.
How to use the awk command in Linux step by step
The examples use a small tab-separated support report. They show how to select fields and calculate a conditional total. A separate program file keeps the final example reusable.
Step 1: Select fields and inspect each record
The program reads tab-separated rows and prints a compact report. NR identifies the heading, while NF checks whether each data row has the expected number of fields.
#!/bin/sh
set -eu
printf '%b\n' \
  'name\tteam\ttickets' \
  'Mira\tplatform\t18' \
  'Omar\tsupport\t7' \
  'Tess\tplatform\t24' |
awk -F '\t' '
  BEGIN { OFS = " | "; print "record", "name", "team", "tickets", "fields" }
  NR > 1 { print NR - 1, $1, $2, $3, NF }
'
Save that source as awk_fields_demo.sh, then run this command from the same directory:
bash awk_fields_demo.sh
record | name | team | tickets | fields
1 | Mira | platform | 18 | 3
2 | Omar | support | 7 | 3
3 | Tess | platform | 24 | 3
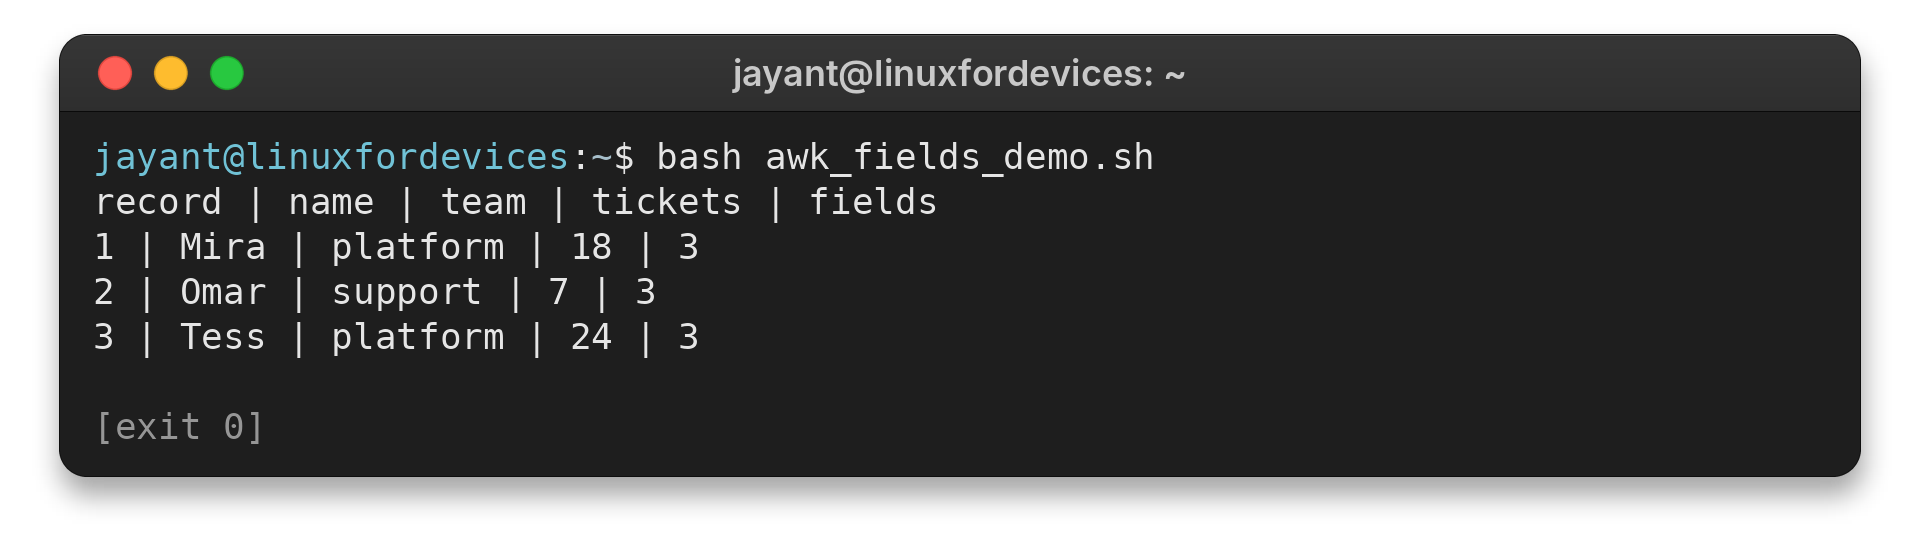
The output uses OFS between printed values, and BEGIN supplies the heading before input rows. All three data rows have three fields.
The rows here use tabs, so spaces within a value do not create another field.
Step 2: Filter records and total a numeric field
This rule keeps support rows with at least 20 tickets and updates the report totals.
#!/bin/sh
set -eu
printf '%b\n' \
  'name\tteam\ttickets' \
  'Mira\tplatform\t18' \
  'Omar\tsupport\t7' \
  'Tess\tplatform\t24' \
  'Noah\tsupport\t31' |
awk -F '\t' -v minimum=20 '
  BEGIN { OFS = " | "; total = 0; count = 0; print "name", "team", "tickets" }
  $3 >= minimum && $2 ~ /support/ {
    print $1, $2, $3
    total += $3
    count++
  }
  END { printf "Matched rows: %d; ticket total: %d\n", count, total }
'
Save it as awk_filter_demo.sh and run:
bash awk_filter_demo.sh
name | team | tickets
Noah | support | 31
Matched rows: 1; ticket total: 31
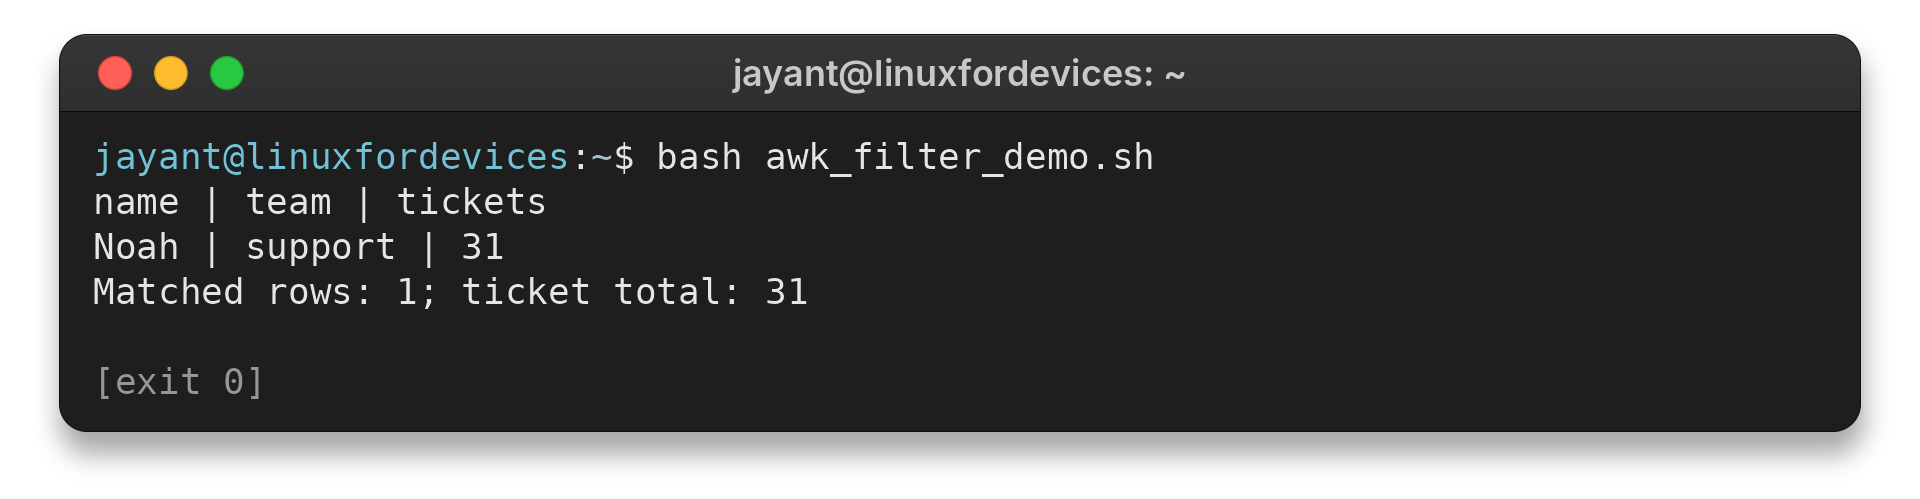
The output contains one match and a ticket total of 31. The -v assignment makes the threshold available to the rule before records are read.
The second test accepts fields containing support. Add anchors when the whole field must match. The threshold comparison uses a number, while the team test uses text.
Check that the field being added contains numeric values. Blank entries or placeholders can make a total misleading, so decide whether to skip them or report them as invalid. This check is useful for operational logs where a dash may represent missing data.
Step 3: Keep a reusable program in an awk file
This program skips the heading and prints a row count after processing the data.
Save the following as awk_report.awk:
BEGIN { OFS = " | " }
NR == 1 { next }
{ print $1, $2; rows++ }
END { printf "Records: %d\n", rows }
The sample has a header and three tab-separated data rows. Run the program file with -f:
event	owner	status
backup	Mira	complete
restore	Omar	queued
backup	Tess	complete
awk -F '\t' -f awk_report.awk events.tsv
backup | Mira
restore | Omar
backup | Tess
Records: 3
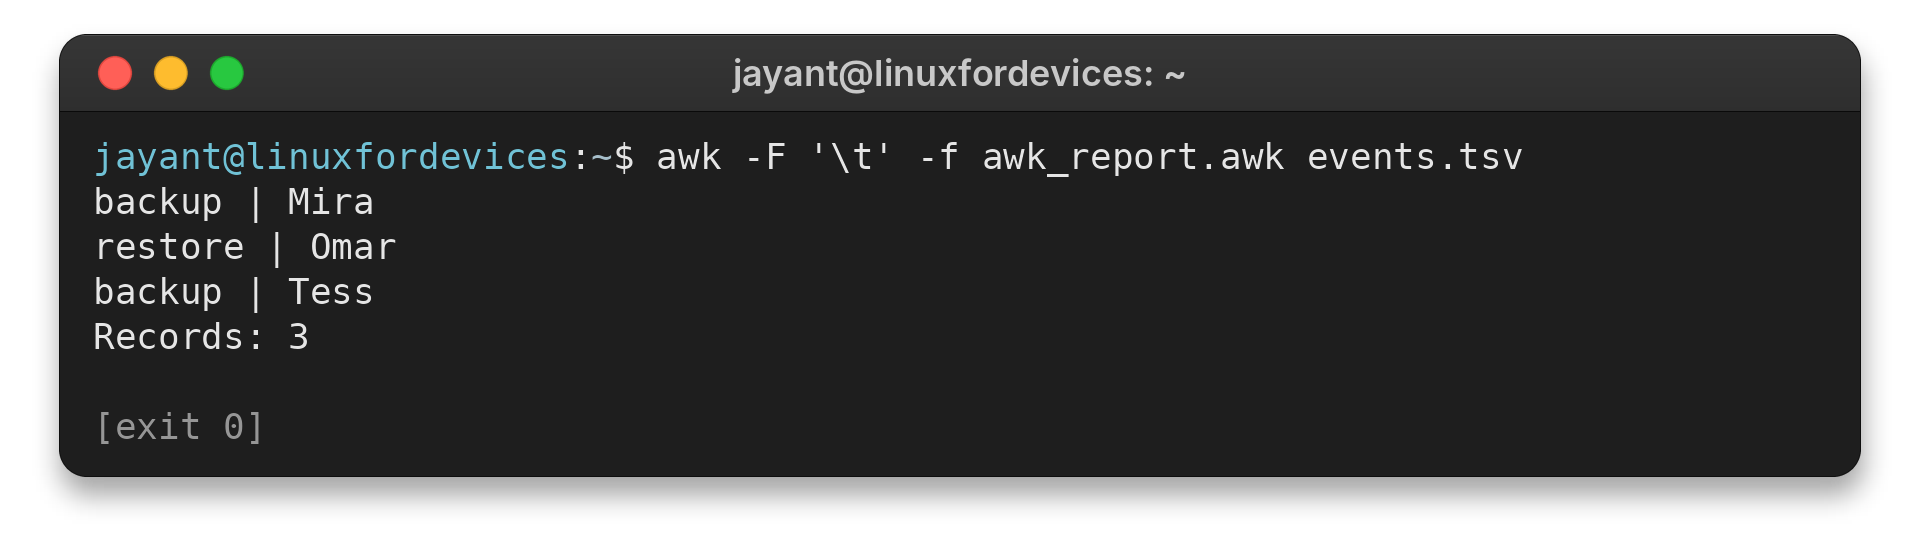
-F sets the tab separator, and -f loads the program file. The first rule skips the header, while the next prints each data row and increments a count. For several files with headers, use FNR to restart the header check for each file.
An awk source file is plain text and can include comments about input assumptions. Relative file names are resolved from the current working directory, so run the command beside the data file or provide a path.
Search lines with a keyword
A regular expression written before the action selects matching records. This form searches every line for the word error, without caring whether the word is in a particular field.
awk '/error/ { print $0 }' application.log
The condition is tested once for each record, and the action prints the whole matching record. Use a field-specific regular expression when the search should be limited to one column. Regular expressions are case-sensitive by default, so an uppercase ERROR does not match the lowercase expression.
Print lines with more than 10 characters
Call length($0) to measure the complete current record, then compare its result with 10. The comparison is greater-than, so a record containing exactly 10 characters is excluded.
awk 'length($0) > 10 { print $0 }' notes.txt
This check counts the characters in the record as awk reads it, not the newline separator. To measure only one field, use length($2). Check that the selected field exists first when rows may have different numbers of columns.
Awk command syntax
The basic form is awk followed by options, a program, and one or more input files. A program contains condition-action rules, written as a condition followed by an action in braces.
awk [options] 'pattern { action }' file
Without a condition, awk applies its action to every record. A condition without an action prints each record that passes the test. The command awk ‘/error/’ file therefore prints lines containing error.
Single quotes protect $1 from shell expansion. Put a delimiter after -F, or load a saved program with -f.
Options belong before the program, and input file names follow it. With no file argument, awk reads standard input. That makes it natural to connect commands with a pipe, but check that the previous command sends the format your field separator expects.
For a quick scan, keep the rule short and inline. Move it to a named .awk file when it has several rules or needs comments, then run it with awk -f program.awk input.txt. This keeps the shell invocation readable while preserving the same rule order.
Start building today
Start with a question about the input: which records qualify, which fields belong in the result, or what value should be counted. Write one rule for that question, try it on a small file, and compare the result with the rows you expect to match.
Then add one operation at a time. A field selection can become a filter, and a filter can update a counter or sum before END prints a summary. Keeping these stages separate shows whether a wrong result comes from splitting, selection, or calculation.
When the report will be reused, save the program beside a sample input and record the expected output in a comment or test fixture. A later change to the input delimiter or header should be checked against that small case before the command is used on a larger log.
Which awk variables and operators help with text processing?
Built-in variables track input position and define how awk splits records or formats output.
| Variable | Use | Default or scope |
|---|---|---|
| $0 | Complete current record. | Rebuilt when a field is changed. |
| Numbered fields | Values within the current record. | Begin at one and end at NF. |
| FS | Input field separator. | Whitespace by default. |
| OFS | Separator inserted by print between values. | The default is a space. |
| RS | Input record separator. | Newline by default. |
| ORS | Separator print appends after a record. | Newline by default. |
| NR and FNR | Record number across all input and within the current file. | Increment as records are read. |
| NF | Number of fields in the current record. | Recomputed when fields change. |
| FILENAME | Name of the input file currently being read. | Useful when processing several files. |
Changing a field changes the corresponding part of $0, and awk rebuilds the record with the current OFS between fields. Assigning a new value to $0 causes the fields and NF to be split again. This matters when an action edits a field and later prints the complete record.
| Function | Use | Effect |
|---|---|---|
| length(text) | Measure a record or field. | Returns its character count. |
| tolower(text) and toupper(text) | Normalize letter case before comparison. | Returns a changed string without altering the source field. |
| split(text, array, separator) | Divide a string into pieces. | Stores the pieces in an array. |
| sub(expression, replacement, target) | Replace the first matching part. | Changes the target value. |
| gsub(expression, replacement, target) | Replace each matching part. | Changes the target value. |
| sprintf(format, values) | Build a formatted string. | Returns text that can be stored or printed. |
When a function changes text, name the value that should change. sub() replaces the first match in its target, while gsub() replaces each match. Passing a field as the target confines the change to that field.
How do print and printf differ?
Use print when OFS should separate the output values, and choose printf when the report needs a specific layout or numeric precision.
| Statement | How it formats output | Line ending |
|---|---|---|
| print with comma-separated arguments | Inserts OFS between the arguments. | Appends ORS automatically. |
| printf with a format string | Uses the format specifiers and corresponding values. | Add a newline in the format string when one is needed. |
printf does not insert OFS or add a newline on its own. Keep the format specifiers in the same order as their values, or columns can receive the wrong data.
Use parentheses to make mixed AND and OR tests clear.
| Test | Meaning |
|---|---|
| == and != | Compare values for equality or inequality. |
| >, >=, <, and <= | Compare numeric values by order. |
| ~ and !~ | Test whether a field matches or does not match a regular expression. |
| && and || | Require both tests or either test to be true. |
| ! | Reverse a Boolean test. |
Use exact equality for a literal value and regular expressions for matching text.
An associative array uses text keys rather than consecutive numeric positions, which suits a report grouped by a field with variable values. Update the value under a key as records arrive. Print keys after input, and sort when stable order matters because awk does not guarantee key order.
Use next when a record should be skipped, as the reusable-file example does with its header. Use exit when a condition should stop further reading. awk still runs END rules after exit, so any summary there can be produced after an early stop.
What edge cases should you check before using awk?
Check how empty fields behave before treating the result as structured data.
| Case | Risk | What to do |
|---|---|---|
| Whitespace input | Spacing that looks like columns may vary between rows. | Use the actual delimiter or a fixed-width-aware tool. |
| Tab-separated input | The default whitespace rule can split on both spaces and tabs. | Set FS to a tab before reading the first record. |
| Quoted CSV values | A comma inside quotes may be mistaken for a field boundary, and quoted fields can contain line breaks. | Use a CSV-aware parser for the full CSV format. |
| Short or blank row | NF may be lower than expected, leaving a field empty. | Check NF before using a required field and decide how to handle missing values. |
| Identifier with leading zeros | A numeric comparison may treat a value such as 007 as a number rather than an identifier. | Compare identifiers as text when the zeros carry meaning. |
| Nonnumeric total field | A blank or placeholder can make arithmetic output misleading. | Validate the field or handle invalid rows separately. |
| No input records | END still runs even though no record updated a counter. | Initialize totals in BEGIN and give the empty case a clear result. |
| Terminal input | Without a filename, awk waits for standard input until it receives end-of-file. | Press Ctrl+D at an empty prompt to finish interactive input. |
| Shell quoting | The shell can expand dollar signs or braces before awk sees them. | Keep a short program in single quotes or move a longer program into a file. |
| Binary or NUL-delimited input | awk reads text records and is not designed for arbitrary byte streams. | Choose a byte-safe or NUL-aware tool for those inputs. |
| Replacing a source file | awk prints transformed text but does not provide a portable in-place edit mode. | Write to a separate temporary file and validate it before replacing the source. |
Before relying on a report, compare its output with the expected result for a small input.
Use the cat and more guide for file inspection, and consult the POSIX awk specification for portable language details.
How can awk count or summarize text?
Choose the record, field, or character measure that matches the question your report needs to answer.
| Task | Approach | Check |
|---|---|---|
| Count records | Read NR in END after all input has been processed. | NR counts records, which are usually lines. |
| Count fields | Add NF for each record and print the total in END. | This counts fields, not necessarily natural-language words. |
| Print the final field | Refer to $NF in the action. | Rows with fewer fields still have a last field, but it may be empty. |
| Find the longest record | Compare length($0) with a stored maximum and retain the record number when it changes. | Choose whether the report needs the length, the line number, or the record itself. |
| Stop at first match | Use a condition to trigger exit after the desired row is found. | END rules still run, so guard any summary that needs a complete scan. |
| Select rows by text | Test a full record or a chosen field against a regular expression. | Decide whether a partial match or a whole-field match is intended. |
An awk field count equals a word count only when the chosen separator divides the input into words. In CSV data with quoted values, commas inside text can make a field total misleading.
For a longest-record report, keep the current maximum length and its record number together. Then decide whether the final output needs the source line itself or only its length.
Changing RS changes which input units NR counts.
The earlier total follows the same workflow. BEGIN sets starting values before input. Each selected row updates them, and END prints the result.
Conclusion
Keep the rule and its input together when you need to rerun the same report.
- GNU Awk User’s Guide explains the GNU implementation and its language features.
- The sed command guide is a useful next stop for line-oriented substitutions.
FAQ
These answers cover common questions about running awk and choosing its input format.
Does an awk rule need a condition?
No. A rule without a condition applies its action to every input record. Add a condition when an action should run only for records that pass a test.
What ends interactive input for awk?
Press Ctrl+D at an empty terminal prompt to send end-of-file. awk then finishes processing the input it received.
Can awk parse every CSV file?
No. A simple comma separator does not handle quoted commas or embedded newlines. Use a CSV-aware parser for files that follow the full CSV rules.