
A link name can point at one release today and another tomorrow. A deploy usually calls that link www/current, and ln -s writes it with one flag deciding what happens when the name is already taken.
Leave out -n and ln treats a directory name as a directory, so the link you meant to replace lands inside the old target. I ran both forms against one tree, and the plain command created a second link.
What a symbolic link stores
A symbolic link is a file whose content is a path, and the kernel reads that path on every access instead of reaching the data directly. That is why the size of a link in bytes matches the length of the path inside it, and why a link can name a file, a directory, or a path that no longer resolves.
The stored path can be absolute or relative, and a relative one resolves against the directory that holds the link rather than the directory you were standing in when you ran the command. I built the demo tree with relative targets for that reason, since a link and its target move together and stay valid.
| Property | Symbolic link | Hard link |
|---|---|---|
| What the second name holds | A path string | The same inode number |
| Can name a directory | Yes | No |
| Can cross a filesystem boundary | Yes | No |
| Target moved or renamed | The link stops resolving | Nothing changes |
| Size on disk | The length of the stored path | No extra blocks for the data |
A hard link shares the file’s inode, so it keeps serving the data after the original name is removed, while a symbolic link only names a path.

What you need before you run ln
The command line takes two operands, and ln reads them in a fixed order. The path the name should point at comes first, and the name to create comes second.
Swap them and the link appears somewhere you did not ask for, which is the mistake behind a lot of confused questions about links landing in the wrong directory.
| Flag | What it changes |
|---|---|
| -s | Create a symbolic link instead of a hard link |
| -f | Remove an existing name instead of failing with File exists |
| -n | Treat the name as a normal file when it is a link to a directory |
| -T | Treat the name as a normal file in every case |
| -v | Print a line for each link created |
| -r | Store a relative path computed from the link’s own location |
Without -s you ask for a hard link, which is the same file under a second name rather than a new name for a path. That works for files on one filesystem, so the kernel refuses the same command across a boundary.
ln releases/app-1/index.html www/hard.html
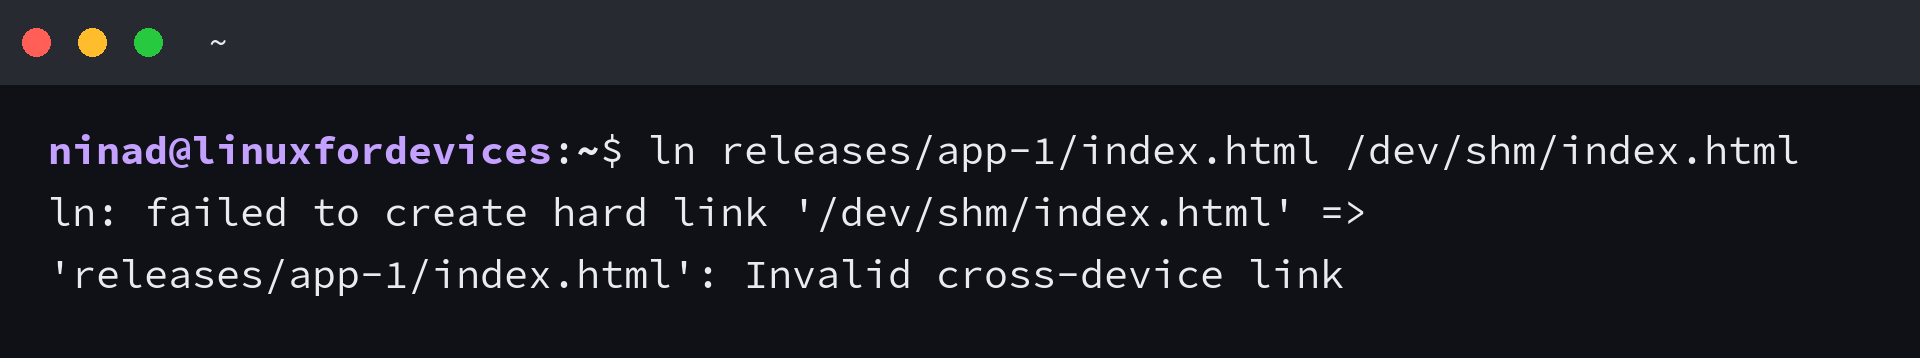
Both names reported the same inode number when I compared them with stat, which is what makes them one file with two entries rather than a copy. The /dev/shm attempt was refused before anything was written, and no flag overrides that boundary, which is the whole reason the -s flag exists.
Create a symbolic link to a file or directory
The command is the same for both, and only the target path changes. The relative form is worth the habit, because a link that stores a relative path keeps working when the whole tree moves together.
Point a link at a file
Give the file’s path first and the new name second. When both operands are long absolute paths, -r works out the relative form that goes inside the link.
ln -s ../releases/app-1/index.html www/index.html
ln -srv releases/app-1 www/auto
Point a link at a directory
A directory takes the same shape, and one command can point at the folder holding every release as well as at the release itself. The name stays put while the directory behind it is replaced.
ln -sv ../releases www/releases
ln -sv ../releases/app-1 www/current
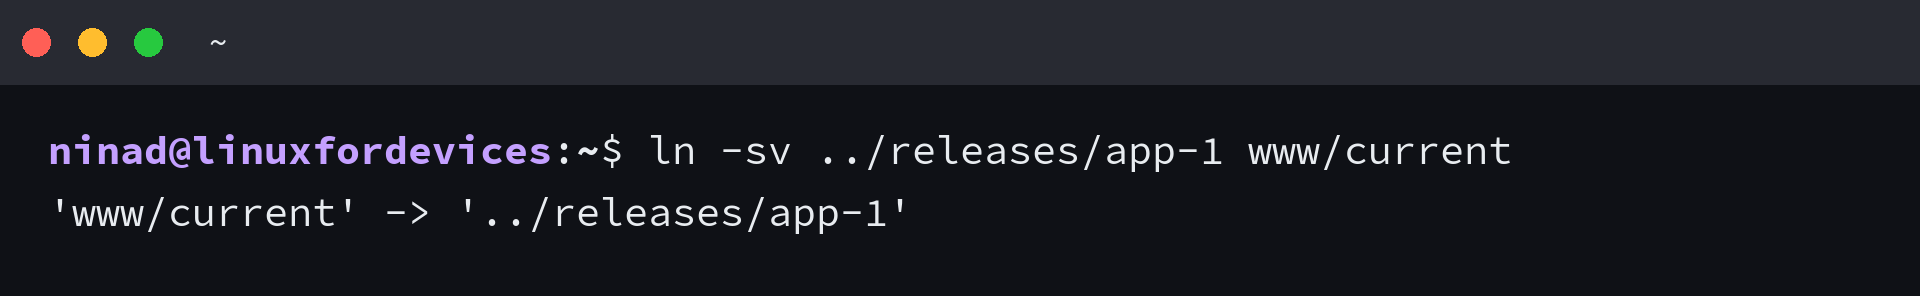
Success is silent without -v, so read the link back instead of trusting the silence. The ls command you already use for any other file tells you the type and the stored path in one line.
Confirm where the link points
ls -l www
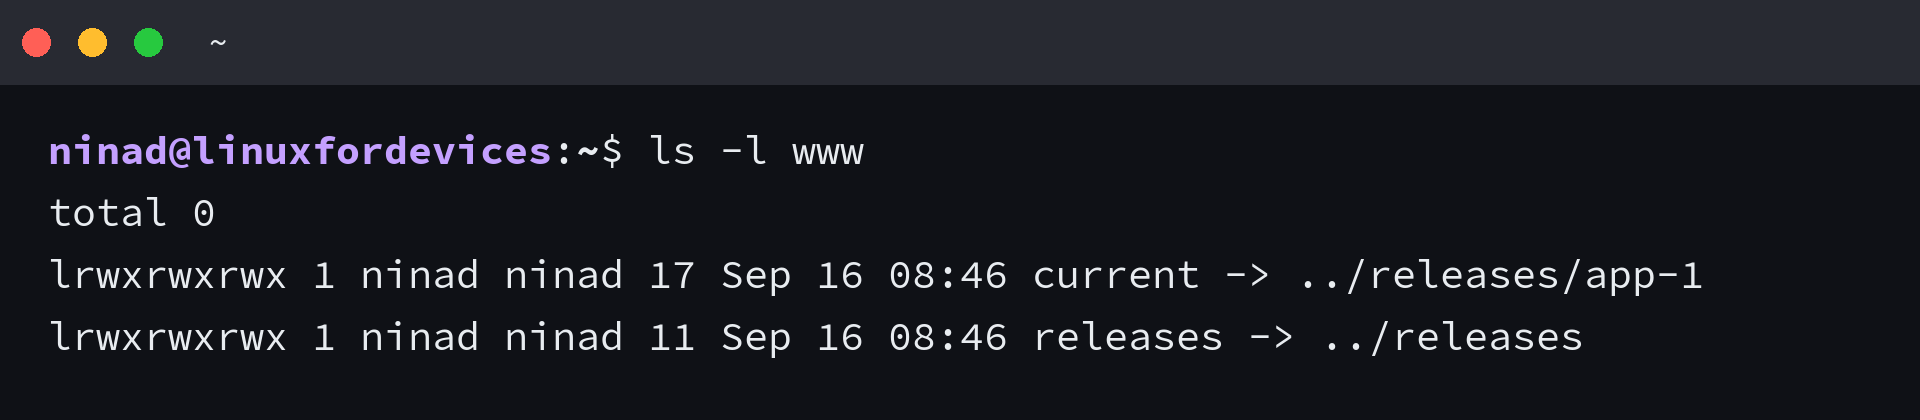
The l in the first column is the file type, and everything after the arrow is the string inside the link. readlink prints that string, while readlink -f resolves it through the filesystem to a full path.
readlink www/current
readlink -f www/current
I read one link with both commands while its target was missing, and only readlink answered. The -f form exits non-zero with no output, while plain readlink still prints the stored string because it never follows it.
A tree of links is quicker to list than to type, and the find command prints each name beside the path it holds.
find www -maxdepth 1 -type l -printf '%p -> %l\n'
Remove a link without deleting what it points at
Removing the name is ordinary file removal, which means the target is not part of the argument. The rm command takes the link and leaves the release directory alone.
rm www/current
unlink removes exactly one name and nothing else, and it takes the same operand as rm. The thing that changes the outcome is a trailing slash on the name, which turns a safe removal into a recursive delete through the link.
unlink www/auto
rm -r www/current/
With -r, that trailing slash makes rm walk through the link and empty the target directory before it reports that the link is not a directory. I ran that form against a throwaway directory and the file inside the target was gone before the error appeared.
Type the name without the slash and rm removes the link alone, which is the form to use in a script.
When ln -s puts the link in the wrong place
The same command behaves differently depending on what the name already resolves to, and neither outcome is announced as an error.
When the name resolves to a directory, ln treats it as the destination directory and writes the new link inside it, named after the basename of the target. A Unix Stack Exchange question describes that exact outcome, a link landing inside the folder it was meant to replace.
ln -s ../releases/app-2 www/current
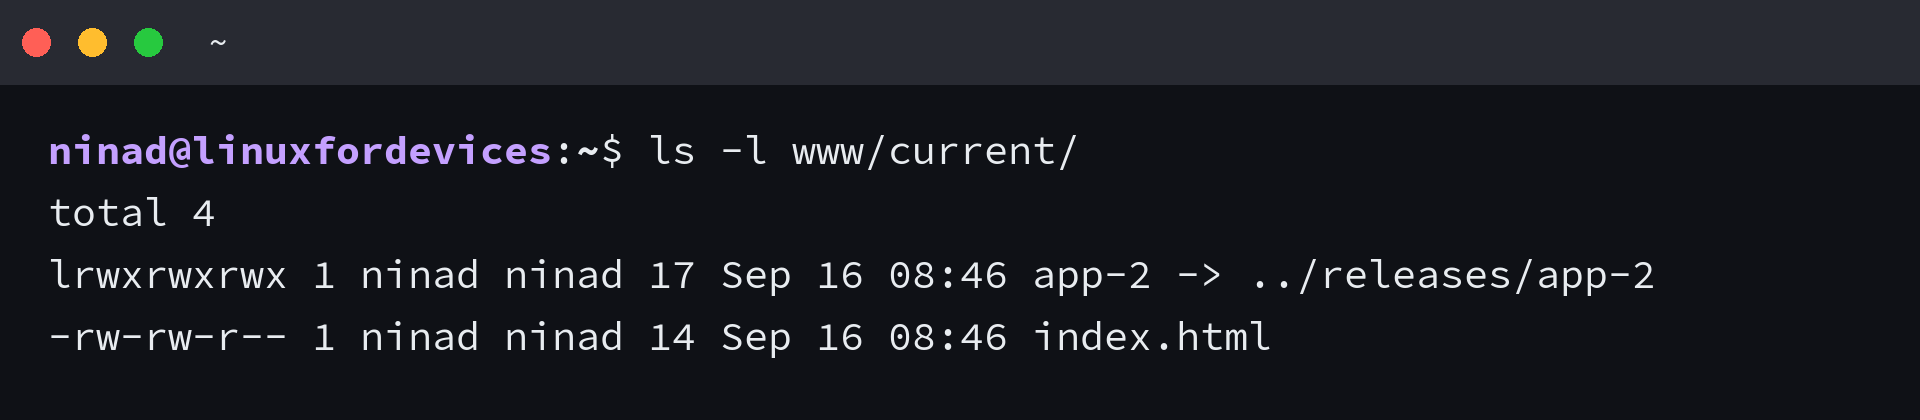
Nothing was printed and the exit status was zero, so the only evidence is the extra entry in the listing. With a relative target that entry is dead as well, because its stored path now resolves from the release directory rather than from www.
Add -f on its own and ln removes whatever already sits inside the target directory under that name, which is how a link command turns into data loss.
ln -sf ../releases/app-2 www/current
I tested that variant against a file named app-2 inside the release directory, and ln replaced the file with the new link at exit status zero. The -f flag clears the name it is about to use, and with a directory link that name lives inside the target.
Add -n and ln treats the name as a normal file instead of a directory, which replaces the link itself. For a directory link this is the combination you want, and -T states the same instruction without the condition attached.
ln -sfnv ../releases/app-2 www/current
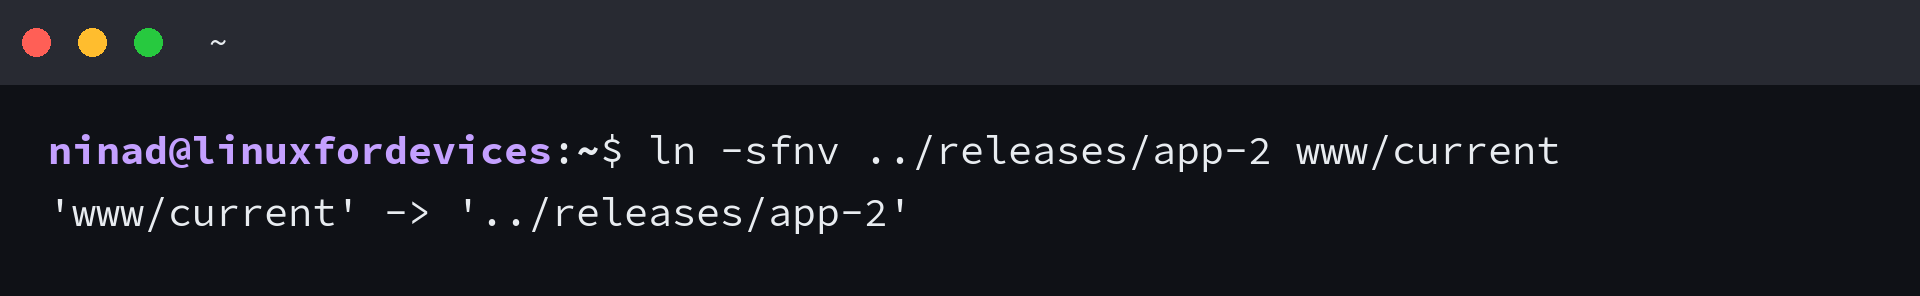
If the name resolves to a file, or to a path that does not exist yet, the plain command stops with File exists and -f is enough on its own.
Repair a link that stopped working
Move, rename, or delete the target and the link is untouched while its stored path stops resolving. The mv command is enough to produce that state.
mv releases releases-old
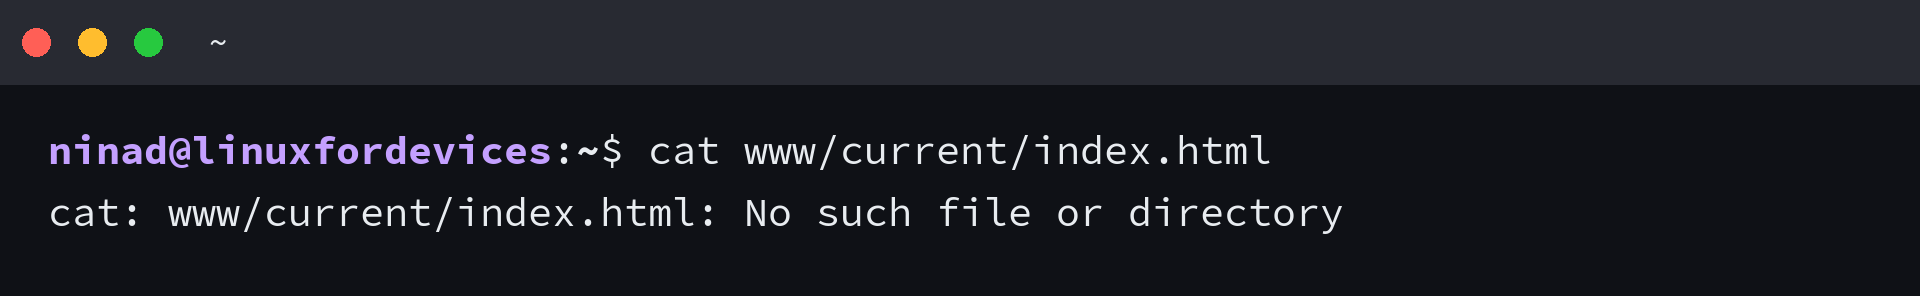
That message comes from the path lookup rather than from the link itself. readlink still prints the stored string in full, and the next table is the shortest way to tell the three states apart.
| State | What you see | What it means |
|---|---|---|
| Live link | ls -l ends in an arrow and a target | The stored path resolves |
| Dangling link | find -xtype l prints the name | The stored path is gone, the link is not |
| Name not a link | ls -l shows a byte size and no arrow | You are looking at the target itself |
find www -xtype l
I moved the release aside, watched the read fail, and then pointed the same name at the directory that exists. The cat command read the new target through the unchanged link, because a link stores a string rather than a copy of the data.
ln -sfnv ../releases-old/app-1 www/current
Because the link holds a path, new content written to that path is served through every link that names it. There is no relink step, and no error if the write went to the wrong path.
Switch a release by repointing one link
Give every release its own directory, keep one link in front of them, and the deploy becomes a command that never touches the data it serves. The filesystem hierarchy keeps the link wherever your web server already looks, and the PATH variable covers the other common use, a binary in /usr/bin pointing at the program installed under /opt.
ln -sfnv ../releases/app-3 www/current
Move the link to another directory and the same stored string points at a different place, which is how a link goes dead without anyone deleting anything. Keep the releases and the link in the same tree for that reason, since a relative target resolves from the directory that holds the link.
I ran that switch against the same tree with a third release directory, and the deploy was a single command. The previous release stays on disk, so a rollback is the same command with the older directory name, and nothing is copied the way the cp command copies it.
A single command changes which release is live, and the only thing that moves is the string inside the link.
Frequently asked questions
How do I check what a symbolic link points to?
readlink prints the stored path exactly as written, and readlink -f resolves it to a full path. ls -l shows the same target after the arrow at the end of the row.
Why did ln -s create a link inside the directory instead of replacing it?
The name you gave already resolved to a directory, so ln treated it as the destination directory and wrote the new link inside it. Add -n to treat the name as a normal file and replace the link itself.
How do I replace an existing symbolic link?
Use ln -sfn with the new target and the existing name. The -f allows the replacement and -n stops a name that points at a directory from being followed instead.
Does deleting a symbolic link delete the target?
No. rm removes the link entry and the file or directory it named stays where it was. The exception is a recursive removal with a trailing slash, which walks through the link and empties the target directory before reporting that the link is not a directory.
Can a symbolic link point to another filesystem?
Yes, and that is one reason to choose a symlink over a hard link, which the kernel refuses across a filesystem boundary with Invalid cross-device link.
What is the difference between a symbolic link and a hard link?
A symbolic link stores a path and can name a directory or a path on another filesystem. A hard link shares the inode of an existing file, so the data survives until the last name is removed, and both names are the same file.