
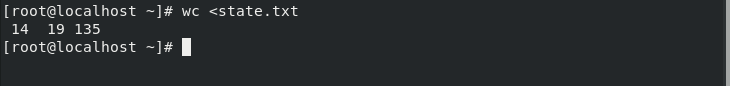
# wc < [filename]
- -w: print the total words
- -l: prints the newline counts
- -m: print the total character by character count
- -c: prints the total characters by byte count
- -L: prints the length of the longest line
- –version: to check the version of the command
A long paragraph can take up three screen rows in your editor while `wc -l notes.txt` counts just one newline-terminated line. I like that this mismatch reveals the difference between displayed rows and what the file stores.
Once that distinction clicks, you can match the count to the question you have. First, see what the command counts by default.
What the wc command counts
The wc command reads a file or standard input and prints counts. With a filename and no options, GNU wc reports newline characters, whitespace-separated words, and bytes, in that order.
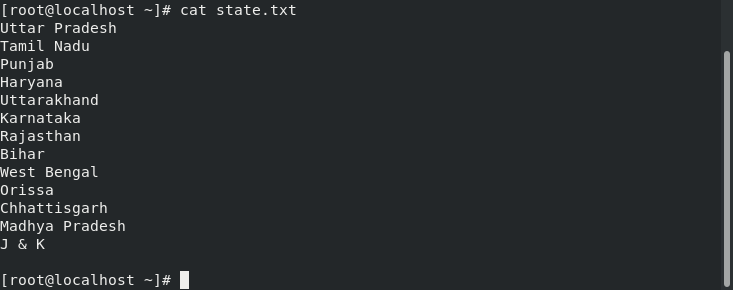
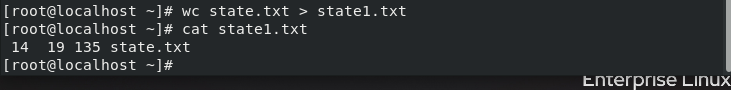
For example, the sample state.txt file has 14 newline characters, 19 words, and 135 bytes. Its trailing spaces count toward the byte total even though they do not add words.
wc state.txt
14 19 135 state.txt
| Column | What it counts | Choose it when |
|---|---|---|
| First | Newline characters | You need a count of newline-terminated records |
| Second | Words separated by whitespace | You need a text word count |
| Third | Bytes in the input | You need its encoded size |
The first number is not a count of screen rows. A terminal can wrap a long line for display, but wc counts newline characters stored in the input.
The file name appears after the numbers when you pass a file as an argument. A manual page for the Linux man command shows how to look up options such as these at the terminal.
Choose the wc count you need
GNU wc keeps selected fields in its documented order, so the option identifies the number even when the file name is absent.
| Option | Output | Boundary |
|---|---|---|
| -l | Newline count | A final record without a newline is not counted |
| -w | Whitespace-delimited word count | Punctuation stays attached to a word |
| -c | Byte count | Includes spaces and newline bytes |
| -m | Character count | Depends on the current locale |
| -L | Maximum display width of a line | Not always the same as its character count |
| –version | GNU wc version information | GNU long option |
Uppercase L and lowercase l do different jobs. Use -L for the widest line and -l for newline characters.
If you are creating a sample file to follow along, the Linux file-creation methods page covers several ways to write one from a shell.
Count lines, words, and the longest line
Use -l when you need newline characters, -w for whitespace-separated words, and -L for the maximum display width. These options keep the command short when you only need one field.
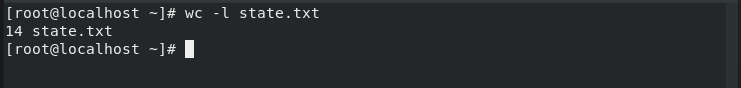
wc -l state.txt
wc -w state.txt
wc -L state.txt
The sample file returns 14 for -l, 19 for -w, and 15 for -L. GNU wc defines the first result as newline characters, so it is a record count only when each record ends with a newline.
The -w option treats a word as a nonempty run of non-whitespace characters. That is why punctuation attached to a token does not create another word.
The sample’s final entry, J & K, counts as three words because whitespace separates the tokens. The ampersand does not create a special boundary for wc.

The -L option reports display width rather than a universal character total. Tabs and wide characters can occupy different display columns, so use -m when the question is about characters.
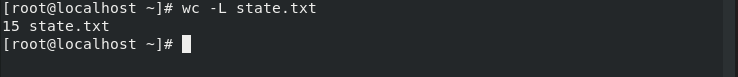
If the file’s newline count is the only value you need, follow the focused Linux line-count procedure instead of reading all three default columns.
Compare bytes with characters
The -c option counts encoded bytes, while -m counts characters as interpreted by the current locale. In UTF-8, one character can use more than one byte.
printf 'café\n' > unicode.txt
wc -c unicode.txt
wc -m unicode.txt
I used café as the test word because its accented letter takes two bytes in UTF-8, so wc -c returned 6 while wc -m returned 5 with the final newline.
| Option | Count for unicode.txt | Meaning |
|---|---|---|
| -c | 6 bytes | Encoded file size |
| -m | 5 characters | Characters under the active locale |
Line endings also occupy bytes. With a carriage return and a line feed (CRLF) ending, -l counts the line feed while -c includes both bytes.
printf 'a\r\n' > crlf.txt; wc -l crlf.txt; wc -c crlf.txt
1 crlf.txt
3 crlf.txt
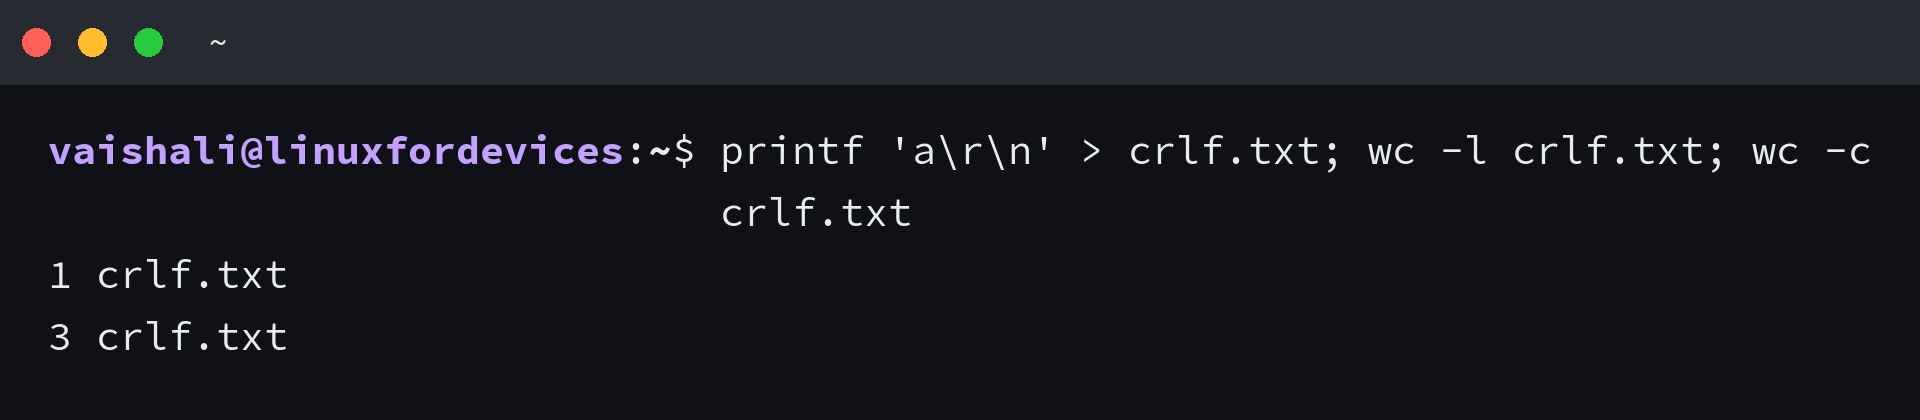
The line feed ends the record, so wc -l reports one. The carriage return still occupies a byte, which is why wc -c reports three.
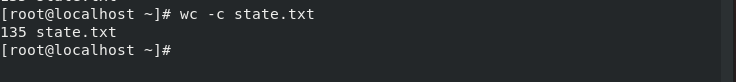
The retained byte and character examples use plain ASCII text, so their totals match. The UTF-8 terminal result below makes the difference visible.
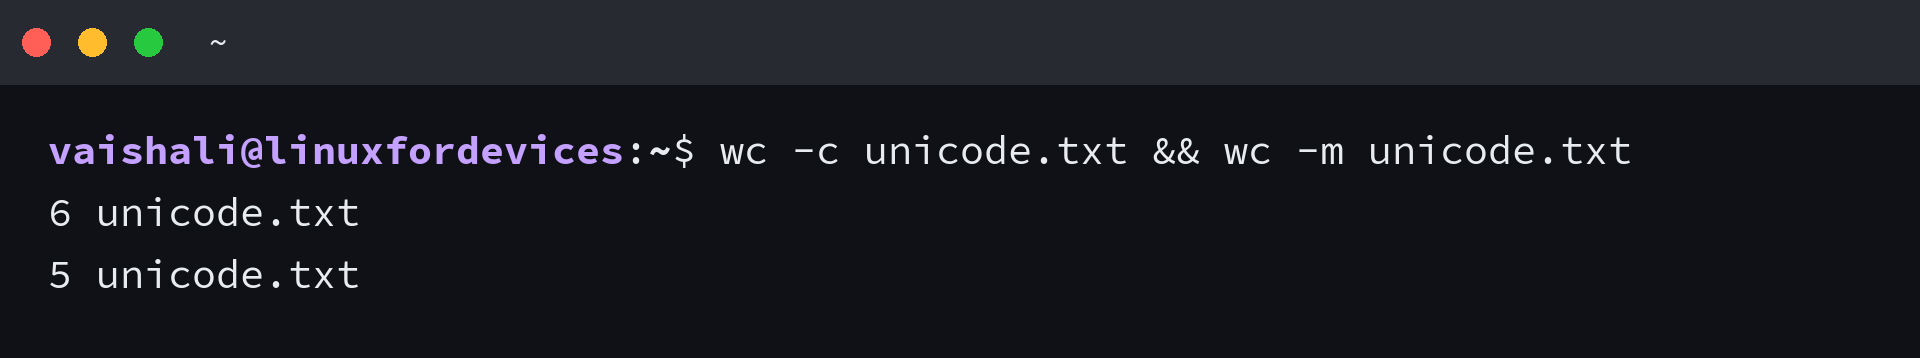
The active locale affects -m. In the C locale, this same GNU command treats each byte as a character and returns 6.
LC_ALL=C wc -m unicode.txt
6 unicode.txt

Read from standard input or several files
With no file argument, wc reads standard input. A pipe sends another command’s output there, while input redirection supplies a file without printing its name beside the counts.
- Pass a filename when you want the output to identify that file.
- Use input redirection when you need the counts without a filename.
- Pipe command output to wc when you need to count the newlines, words, or bytes it emits.
wc < state.txt
printf 'one\ntwo\n' > file-a.txt
printf 'three\n' > file-b.txt
wc file-a.txt file-b.txt
GNU wc prints one row per file and a total row, while -L reports the widest line rather than a sum.
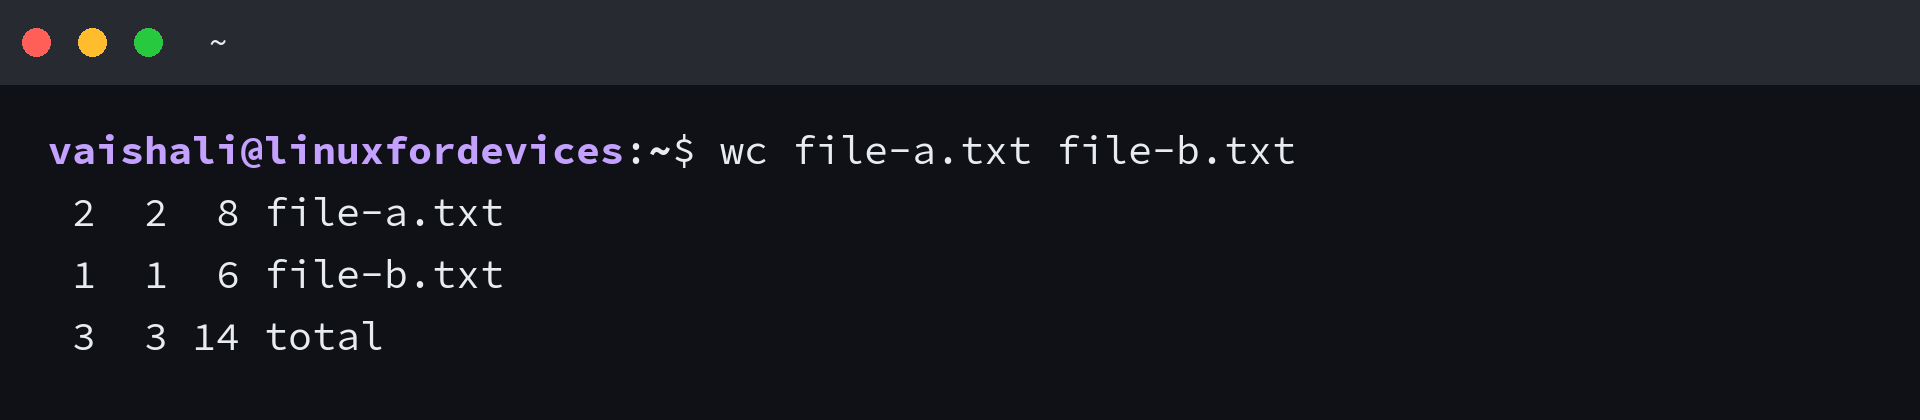
The total row adds the selected line, word, and byte counts. For -L, GNU wc reports the widest line instead, because widths are not additive.
The Linux cat and more commands can show the text sent through a pipe. Directory listings produce their own input stream, so use the page on counting files in a directory when that is the task.
Save counts and use wc in a pipeline
Use output redirection when a later command or script needs the count report in a file. The greater-than operator creates the destination or replaces its contents.
wc state.txt > counts.txt
cat counts.txt
The saved line still names state.txt because that is the input file. This is different from wc < state.txt, which reads the same file through standard input and omits its name.
On an RPM-based distribution, rpm -qa lists package records, so rpm -qa | wc -l counts those records rather than applications across every Linux system.
rpm -qa | wc -l
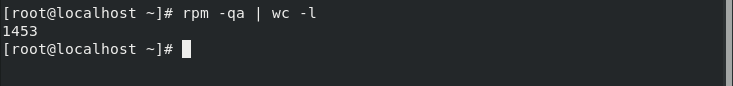
The rpm query is distribution-specific. On Ubuntu, use its APT installed-package commands to inspect package records instead of copying the RPM command.
When a count differs from the file you see
The -l option counts newline characters, not visual rows in an editor. I wrote a file containing the word line without a final newline, then ran wc -l. It returned zero even though the file contained text.
printf 'line' > no-final-newline.txt
wc -l no-final-newline.txt
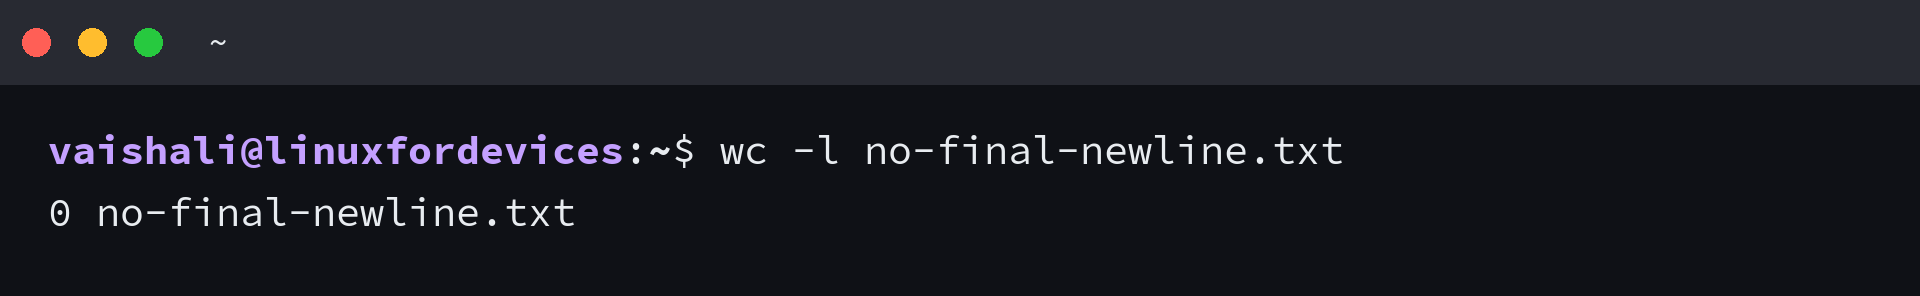
Add a newline if the file should end with a complete text record. If the number needs to match the editor’s visible rows, check whether the final record has a line ending before treating the output as an error.
Adding that final newline changes the count by one and marks where the record ends.
- Trailing spaces add bytes and can widen a line without adding words.
- Character counts depend on the active locale, while byte counts follow the encoded file.
For scripts, redirect input when you need a bare number, and keep the final-newline rule in mind when counting records.
Let the count match the question
Pick the measurement first. A newline count, a word count, a byte size, and a display width answer different questions, even when they come from the same file.
wc -l state.txt
Frequently asked questions
These answers cover the two points that change how you interpret a wc result.
Does wc -L print the number of characters in the longest line?
No. GNU wc reports the maximum display width. Tabs and wide characters can occupy a different number of columns than characters in the file.
Can wc count records from another command?
Yes. Pipe the command output to wc -l to count its newline characters. A final record without a newline is not included in that count.