
You have text to replace and want the match to work regardless of capitalization. sed searches input text and can replace matches, and its i substitution flag makes the search ignore capitalization.
I’ll show how to choose the substitution flags and check the output before an in-place edit.
TL;DR: Ignore Case with sed
For a case-insensitive substitution, put the i flag after the replacement. Add g when you want every match on each line changed. POSIX specifies lowercase i, and GNU sed also accepts uppercase I.
- First match per line: sed ‘s/error/NOTICE/i’ app.log
- Every match per line: sed ‘s/error/NOTICE/gi’ app.log
- -i edits the file in place. It does not mean “ignore case.”
What Does Ignore Case Mean in sed?
Use lowercase i after the final substitution delimiter to match search letters without regard to case, as in s/error/NOTICE/i. Enter the replacement text with the capitalization you want in the output.
| Syntax | What it controls | Scope |
|---|---|---|
| i after a substitution | Case-insensitive regular-expression matching | POSIX substitution flag |
| I after a substitution | Same matching behavior in GNU sed | GNU accepts it as an uppercase alias |
| g after a substitution | All matching occurrences instead of only the first | Each input line |
| -i before the sed script | Writes changes back to the input file | File write behavior |
| /expression/I as an address | Selects lines with a case-insensitive regex | GNU-specific address extension |
Read a substitution as s/regexp/replacement/flags. The first field is the search expression, the second is the text to insert, and flags follow the final delimiter. Options such as -i go before the script, so position shows whether the letter changes matching or file output.
A simple search for error can also match inside terror because sed looks for a substring. POSIX sed has no portable word-boundary escape, so whole-word matching needs an explicit boundary expression or context. Test that expression with punctuation and the locale used on the target system.
A replacement can reuse text captured by a group in the search expression. A numbered backreference inserts those captured characters in the replacement. Use a fixed replacement when the output should have a consistent spelling instead.
How to Use sed to Ignore Case
Start by letting sed print transformed text to the terminal. The tested example below creates small sample files in the current directory, compares first-match and global substitutions, checks a GNU address, and then saves an in-place edit with a backup. Run it from a directory where creating those two sample files is appropriate.
Step 1: Run a repeatable example
Save this script as sed_ignore_case_demo.sh, then run bash sed_ignore_case_demo.sh. Its input contains three case variants on one line and one matching word on another. GNU sed is needed for the uppercase flag and address examples.
#!/bin/sh
set -eu

input='sed-ignore-case-input.txt'
printf '%s\n' \
  'Error ERROR error' \
  'Warning: error found' \
  'No issue on this line' > "$input"

printf '%s\n' 'Input:'
cat "$input"
printf '\n%s\n' 'First case-insensitive match per line:'
printf '%s\n' "$ sed 's/error/NOTICE/i' $input"
sed 's/error/NOTICE/i' "$input"
printf '\n%s\n' 'Every case-insensitive match per line:'
printf '%s\n' "$ sed 's/error/NOTICE/gI' $input"
sed 's/error/NOTICE/gI' "$input"
printf '\n%s\n' 'Lines selected by a GNU case-insensitive address:'
printf '%s\n' "$ sed -n '/error/Ip' $input"
sed -n '/error/Ip' "$input"
printf '\n%s\n' 'In-place edit with a backup:'
printf '%s\n' 'Error ERROR error' > sed-ignore-case-edit.txt
printf '%s\n' "$ sed -i.bak 's/error/NOTICE/gi' sed-ignore-case-edit.txt"
sed -i.bak 's/error/NOTICE/gi' sed-ignore-case-edit.txt
cat sed-ignore-case-edit.txt
printf '%s\n' 'Backup preserved:'
cat sed-ignore-case-edit.txt.bak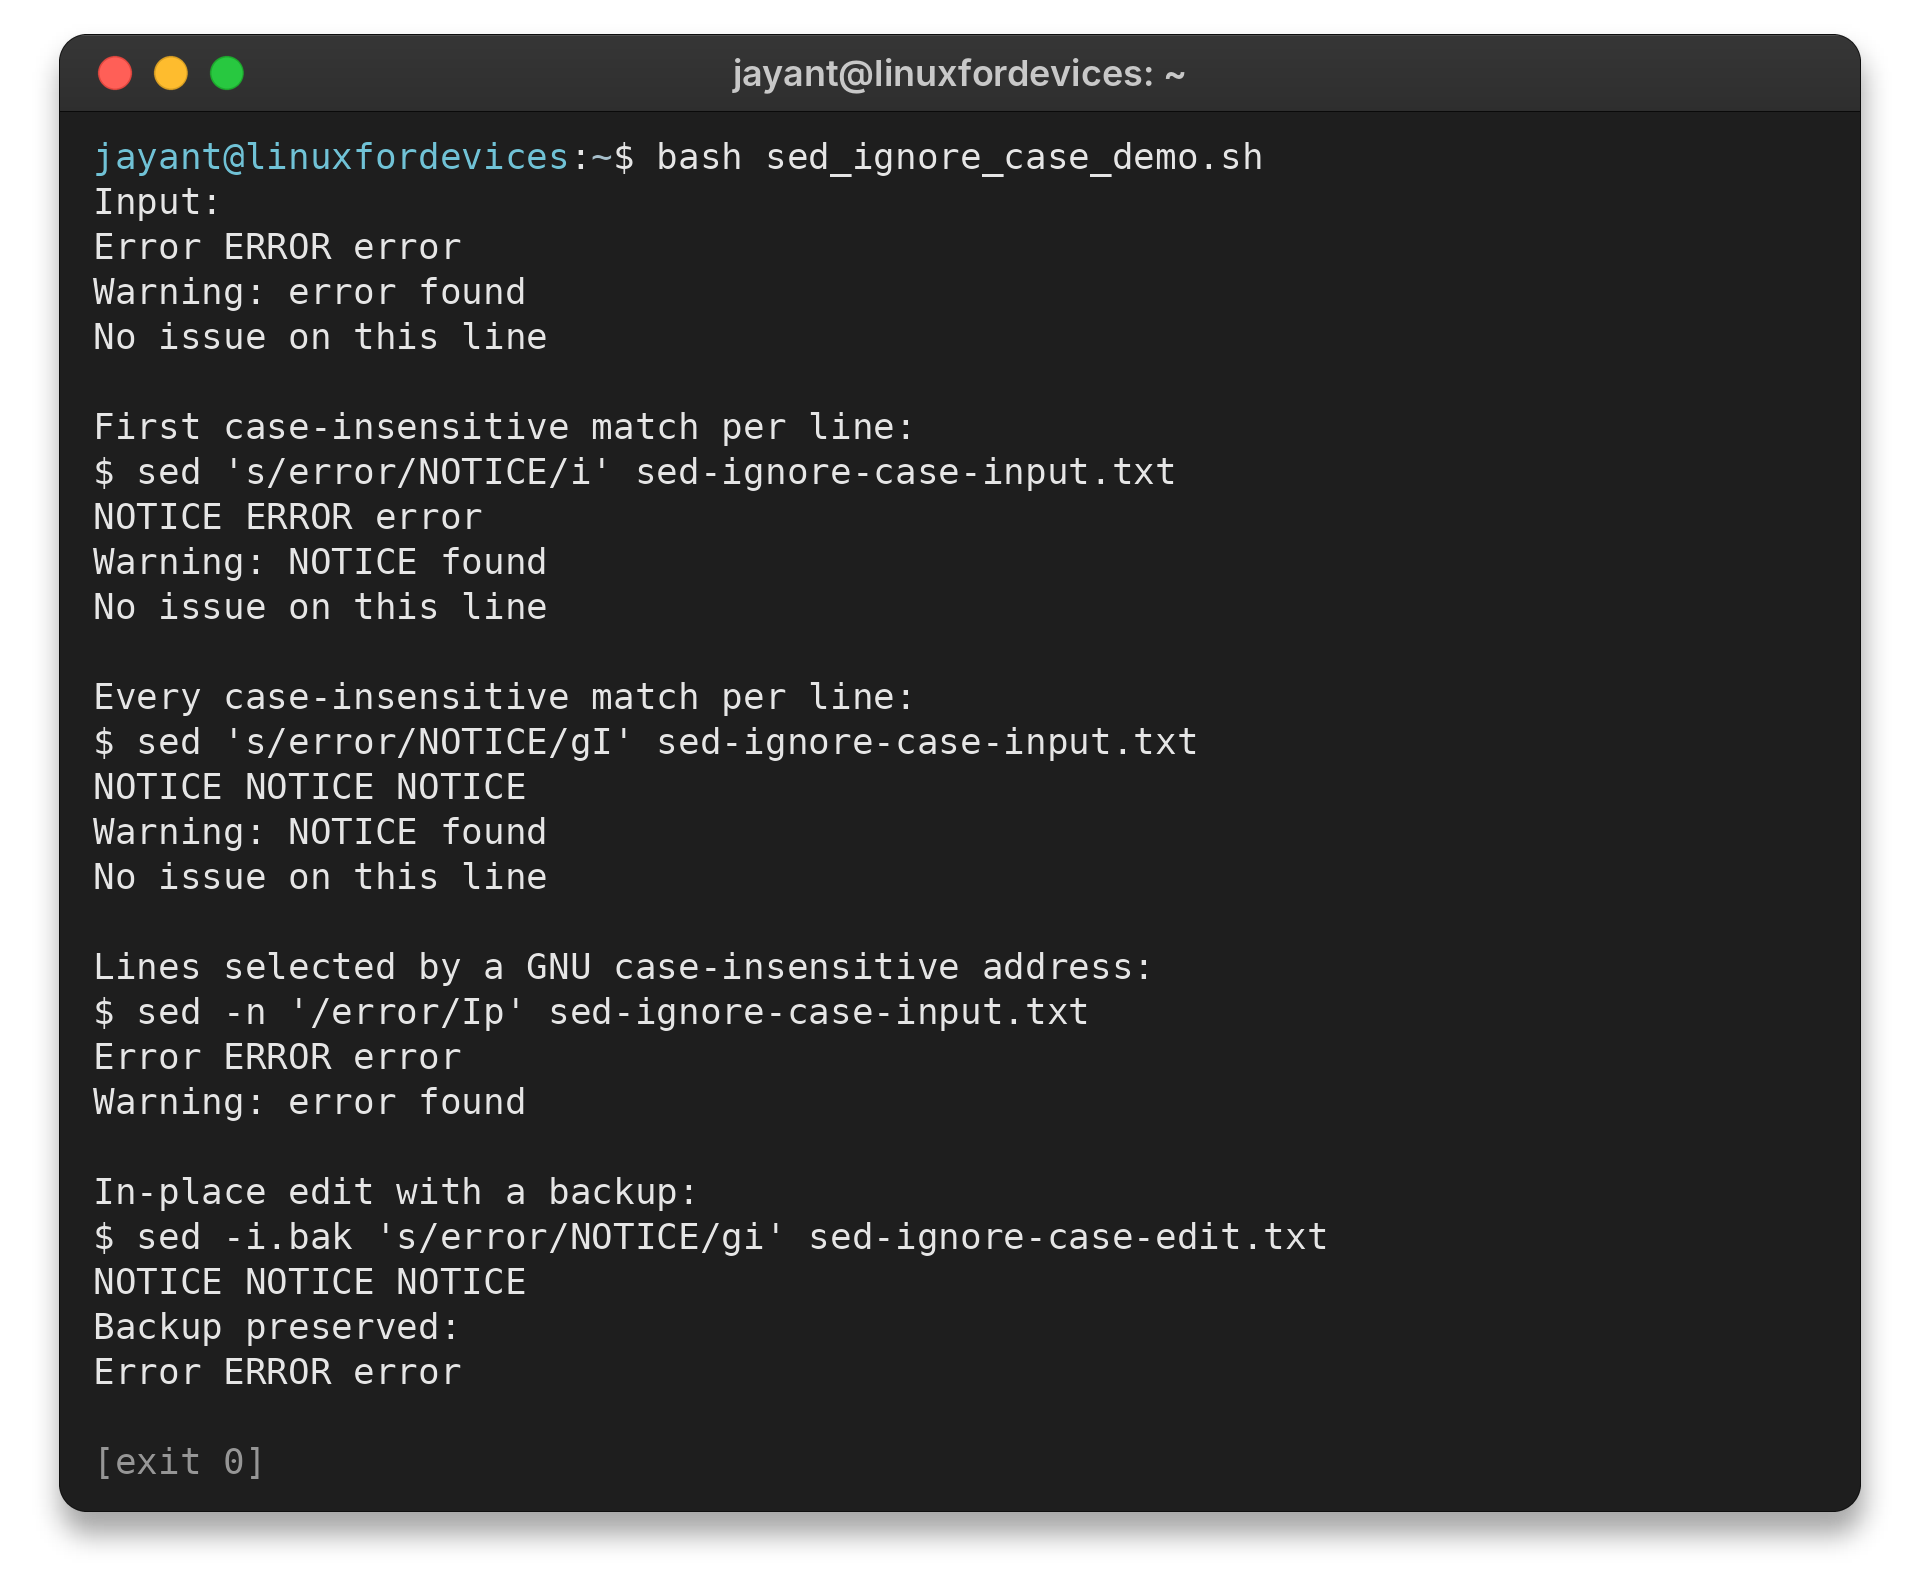
The terminal run produced this complete output:
jayant@linuxfordevices:~$ bash sed_ignore_case_demo.sh
Input:
Error ERROR error
Warning: error found
No issue on this line

First case-insensitive match per line:
$ sed 's/error/NOTICE/i' sed-ignore-case-input.txt
NOTICE ERROR error
Warning: NOTICE found
No issue on this line

Every case-insensitive match per line:
$ sed 's/error/NOTICE/gI' sed-ignore-case-input.txt
NOTICE NOTICE NOTICE
Warning: NOTICE found
No issue on this line

Lines selected by a GNU case-insensitive address:
$ sed -n '/error/Ip' sed-ignore-case-input.txt
Error ERROR error
Warning: error found

In-place edit with a backup:
$ sed -i.bak 's/error/NOTICE/gi' sed-ignore-case-edit.txt
NOTICE NOTICE NOTICE
Backup preserved:
Error ERROR error
Step 2: Choose whether to replace one match or every match
In the first result, sed ‘s/error/NOTICE/i’ changes only the first matching word on a line, even though the input has three case variants. The next command, sed ‘s/error/NOTICE/gI’, adds g to change every match on that line.
Step 3: Match whole lines with a GNU address
An address expression selects input lines for a following sed command. GNU sed accepts /error/I to select lines regardless of capitalization.
The full command sed -n ‘/error/Ip’ uses p to print each selected line. The -n option suppresses sed’s automatic output, so the example filters lines without changing their text.
Step 4: Save the result only after checking it
Without -i, sed writes transformed text to standard output and leaves the input file unchanged. That makes the first command straightforward to review before saving its result elsewhere.
On GNU sed, attach the backup suffix to -i as -i.bak. It appends .bak to each input filename, and the captured output compares the changed file with that copy. Other sed implementations may use different in-place syntax, so check their documentation before sharing the command.
GNU sed normally replaces a symbolic link itself during an in-place edit. The --follow-symlinks option asks it to edit the target instead, so check the path and manual before using -i on a link.
Step 5: Apply the script to several files
You can pass several paths to one sed invocation, and the same script runs on each file. Standard output combines the results, so a line may not reveal which input produced it. Review the file list before using -i with a glob, and preserve backups when editing a batch.
sed Ignore-Case Limits and Common Mistakes
To diagnose a surprising result, locate each flag in relation to the substitution delimiters and the sed options.
| What goes wrong | Why it happens | What to check |
|---|---|---|
| “Bad flag” after a substitution | The sed build may use a different set of accepted flag spellings. | Use the case flag documented for the target implementation. |
| Only one word changes | Case handling and replacement count are separate flags. | Add g when every occurrence on a line should change. |
| No lines print with an address | -n suppresses automatic output. | Use a printing command such as p after the address. |
| A line-selection command fails elsewhere | The address form shown here is a GNU extension. | Use GNU sed for that address form, or choose a portable strategy for the target system. |
| A path breaks the substitution | The default slash delimiter also appears in the expression or replacement. | Choose a different delimiter, such as #, and escape it if needed. |
| Accented or non-ASCII text behaves unexpectedly | Character case rules can depend on the active locale and implementation. | Test representative input under the locale where the script will run. Do not assume ASCII-only results cover every language. |
I keep these edge cases together because they affect portability, match boundaries, and replacement text.
On an implementation without the case-insensitive substitution flag, spell both forms of each letter in brackets, as in [Ee][Rr][Rr][Oo][Rr]. This works for a short fixed term but grows with its length and does not scale to an arbitrary expression.
Choose the regular-expression form
Sed uses basic regular expressions by default. GNU sed accepts -E to switch to extended expressions.
| Mode | Group expression | Reference in replacement |
|---|---|---|
| Basic (default) | \(error\) | \1 |
| Extended (-E) | (error) | \1 |
Anchors such as ^ and $ mark the current line’s beginning and end, and an empty line has both. The case flag does not make a normal substitution cross a newline, while GNU sed’s N command can read the next line into its working buffer and change how anchors and output separators behave. Treat N as a separate multi-line design and test it on representative records before editing files.
The shell reads the command before sed. Single-quote the expression to prevent expansion of variables and globs, but sed still interprets its regular-expression syntax. If input data is inserted into a search or replacement, escape it for that field because each side treats special characters differently.
Slash is the default substitution delimiter. A path or URL with slashes can use another, such as s#/var/log/error#NOTICE#i, and that delimiter should be escaped if it occurs in either field. Locale can affect case mapping and character ranges, so test non-ASCII input under the target locale and remember that a successful sed exit code alone does not prove the expression matched.
Conclusion: Use sed’s i Flag for Substitutions
Choose the flags for the sed implementation and the exact match you need. Use the references below when you need to check a detail about the substitution or address syntax.
- GNU sed manual: the substitution command
- POSIX sed utility specification
- Linux terminal-based text editors for choosing an interactive editor.
- Vim search and replace for an editor-based workflow.
FAQ
These answers focus on the flags and matching behavior used above.
Does sed support case-insensitive substitution?
Yes. Put lowercase i after the replacement in the substitution flags, as in s/error/NOTICE/i. POSIX specifies lowercase i. GNU sed also accepts uppercase I.
How do I replace every match regardless of case?
Add g as well as the case-insensitive flag, for example s/error/NOTICE/gi. The i flag controls case matching, and g replaces every match on each line.
Can sed select lines without regard to case?
GNU sed supports a case-insensitive address such as /error/Ip, which selects and prints matching lines. This address modifier is a GNU extension, not a POSIX portable address flag.
Why does sed report a bad i flag?
Check which sed implementation your shell calls and whether that version accepts the substitution flag. POSIX specifies lowercase i, while older or differently built programs may reject it. GNU sed also accepts uppercase I.